Voice AI Isn't Plug-and-Play - Your People Decide the Output
Five articles of architecture - and in the end the people in front of it decide. The loop that makes voice AI better or worse, and why operating literacy is the lever with the biggest multiplier.
For five articles this was about architecture. RAG versus tool calls. The interface above the stack. The governance layer. The runtime that reconciles speed and depth.
All technology. To close, the most uncomfortable part - the one no architecture solves.
The best voice system delivers poor results if the people in front of it operate it poorly. And then the same thing always happens. The operator doesn't get the blame. The technology does. "We tested it, it's no good." Project buried.
The loop that decides success
Voice AI isn't a device you switch on. It's a learning system. Learning systems stand in feedback with their users.
The loop has five stages. It amplifies in both directions.
Better operating literacy. Users ask clear questions. They know where an answer came from. They have a feel for confidence. They give clean feedback.
Better interactions. Clearer inputs. Less ambiguity. More context. More precise corrections.
Better data. Higher quality. Better tagged. Clean evidence. Less noise and fewer duplicates.
Better knowledge. Sharper knowledge objects. Clearer ownership. Stronger patterns. Reusable insight.
Better answers and decisions. Faster retrieval. More reliable answers. Better compliance.
And here's the kicker: better results raise trust. Trust improves feedback quality. Feedback improves literacy.
Operate it well and you improve the system that serves you. Operate it poorly and you drive the loop the other way. Then blame the machine for your own input.
The same question, two worlds
Second-quarter revenue. One last time.
The bad version: "how are things going?" The system guesses - which period, which metric, which unit - and delivers something plausible. The user accepts it, or discards it in irritation. Either way the system learns nothing.
The good version: "give me net revenue for the Swiss entity in Q2 against the same quarter last year, excluding intercompany." Precise question. Clear context. Verifiable answer. If something's off, the practiced user corrects it specifically - and hands the system exactly the signal that makes it better.
Same tool. The difference in output lies almost entirely in the competence in front of it.
That isn't a weakness of the technology. It's its nature. Ignore it and you buy an expensive system and feed it garbage.
Why this matters in the mid-market
In the mid-market the technology is rarely missing. The guidance almost always is.
Tools get introduced. A training session gets ticked off. Then transformation is expected.
With classic software that goes tolerably. Operated wrong, it still behaves predictably. With a learning system it's fatal. Poor operation degrades not just the single answer, but through the loop the entire data foundation.
Operating literacy isn't a user training on the side. It's the lever with the biggest multiplier in the whole project. And the only one you can't buy. Only build.
The fewer specialists you have, the more this applies. A corporation affords a team that optimizes operation. In the mid-market the same people carry daily business and are supposed to learn, on the side, how to handle a learning system.
Without guidance the same thing happens almost every time. One or two enthusiasts use it properly. The rest try it once, are disappointed, and return to the old way of working. The investment evaporates.
Where we stand
Here the circle closes. The architecture is the necessary condition. Your people's operating literacy is the sufficient one. Both have to come together. Otherwise the best system leaves you with a disappointed pilot.
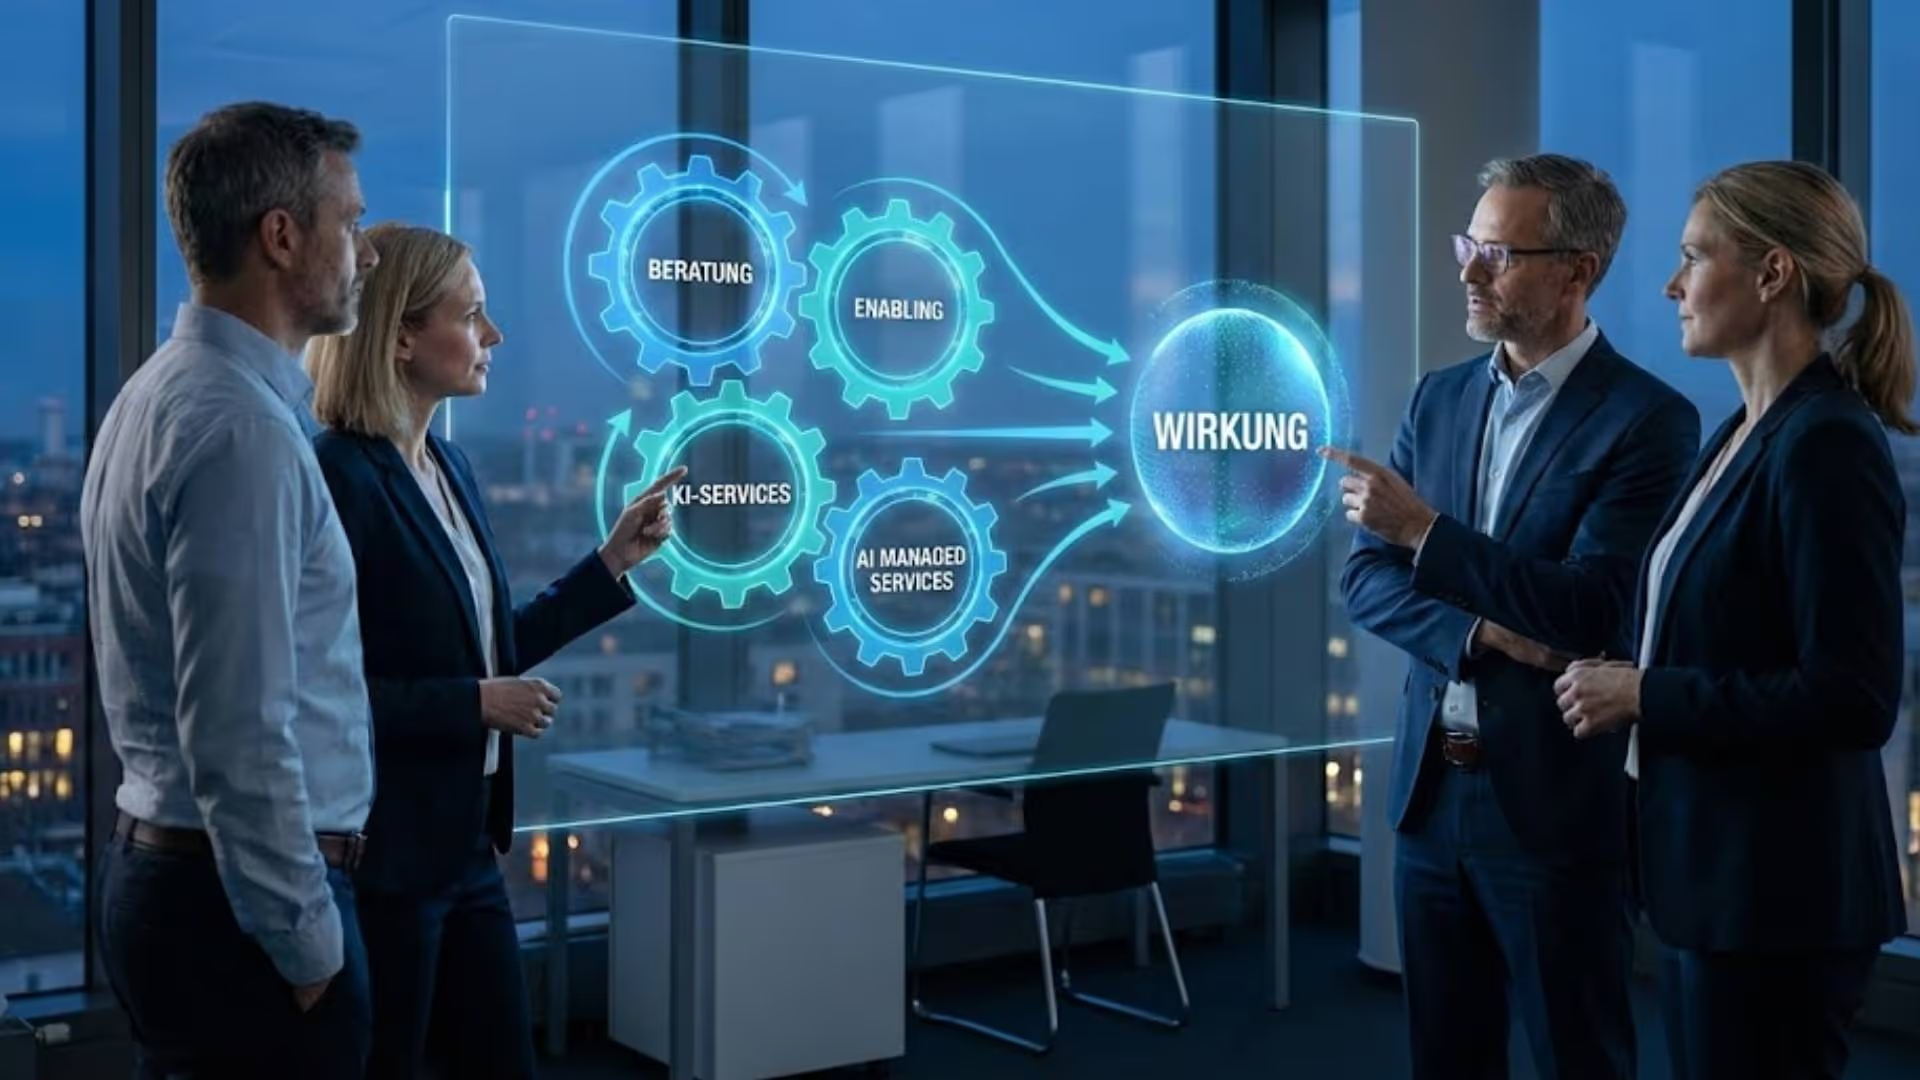
That's what our enabling is for. We don't hand you a tool and wish you luck. We build with your team the competence that decides the output. Clear questions. Source awareness. A feel for confidence. Clean feedback. Governance behavior.
That's the unspectacular part. It makes the difference between an expensive experiment and a system that gets better every week.
Concretely that doesn't mean "one training and done." It means a handful of measurable habits. Ask precisely instead of vaguely. Ask for the source on answers that matter. Don't trust an uncertain answer blindly. Correct errors deliberately instead of clicking them away. Recognize sensitive content before it enters the system.
These habits can be observed and improved. In the quality of the questions. In the correction rate. In the number of answers the team actually trusts.
Operating literacy isn't a soft factor. It's trainable and measurable, if you take it seriously.
Your next step
You have the whole map. Why RAG alone isn't enough. What voice can really do. Where you start today. What makes it reliable. Why it's fast enough. And who decides the quality in the end.
The last step isn't another tool. It's the guidance that turns possibility into impact.
Let's work out what voice AI literacy looks like in your team - from self-check to guided rollout. The best system in the world is only as good as the hands that operate it. And those aren't built overnight.
Links
Here you can find more information
Our Stance. No Bullshit.
We filter out the noise. Here you'll find our unvarnished opinion on AI, scaling, and efficiency. No empty buzzwords. Just the 20% that truly make a difference.
Facts, not assumptions.
Forget gut feelings. Use data. We provide you with the tools to not only see AI potential, but to calculate and scale it.
Ready for a system instead of piecemeal solutions?
Take your focus to the next level.
We integrate strategy, enablement, and technology into a single unit. For lasting results.
Schedule a Focus Check.